Minsik Oh

I’m a master’s student in Computer Science at Stanford University, advised by Yejin Choi and Douwe Kiela. Currently, I’m doing alignment research with Dylan Hadfield-Menell at MIT.

I’m interested in how language models can adapt to different people, values, and preferences. My research interests include pluralistic alignment, personalization, multi-agent systems, post-training (RL), synthetic data, LLM evaluation, and representation learning.

Previously, I worked with the Alexa and AWS AI teams.

Selected research

All publications (11) ↓
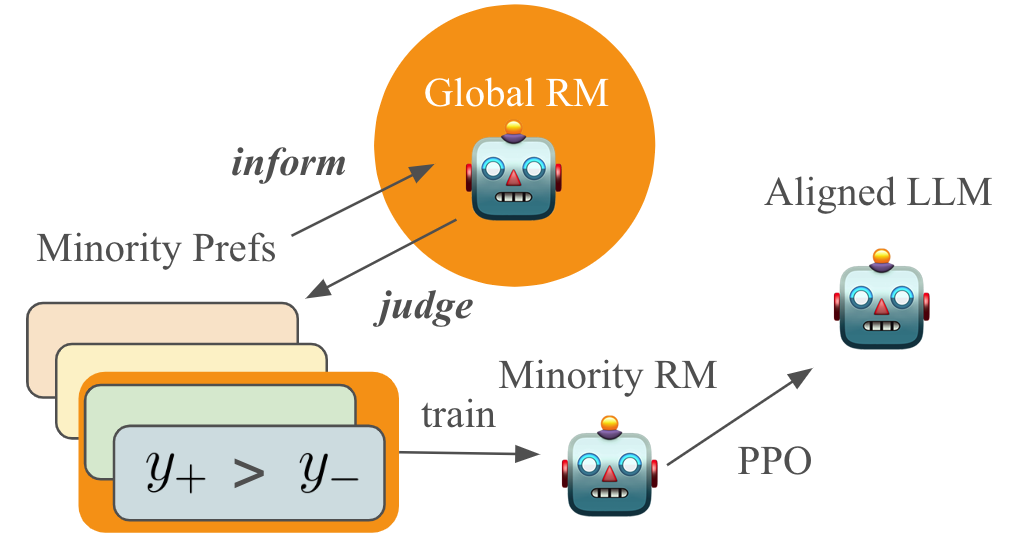
SCPO pipeline: a global reward model guides filtering and weighting of cultural preference pairs before reward-model training.

Pluralistic alignment

Steerable Preference Optimization of Reward Models

Minsik Oh, Advit Deepak, Sophie Wu, Douwe Kiela, Ekaterina Shutova

Pluralistic Alignment @ ICML · 2026

SCPO trains reward models for diverse cultural preferences by filtering and weighting country-specific feedback, improving data efficiency while moderating excessive preference bias.
Publications

Google Scholar